
Tuesday at NetApp INSIGHT 2026, George Kurian called NetApp Novus the biggest announcement the company has made in over a decade, putting it alongside the introduction of the Data Fabric back in 2013/2014. That’s a bold claim, and CEOs are paid to make bold claims, but after sitting through the keynote and reading everything I could get my hands on afterwards, I’m inclined to at least hear him out. Novus isn’t a new controller or a new licensing bundle; it’s a new storage architecture aimed squarely at the gigawatt-scale AI factories being built by Neoclouds, hyperscalers, GPU-as-a-Service providers and the handful of enterprises building their own GPU clouds.
The headline numbers are 100TB/s of aggregate throughput and a single namespace at zettabyte scale. Yes, terabytes per second, and yes, zettabytes. I’ll come back to both.
The problem: it’s the metadata, stupid
Before getting into what Novus is, it’s worth understanding what NetApp says it’s solving, because this is where the keynote was at its best.
NetApp’s math goes like this: a single modern GPU can want as much as 2GB/s to stay busy, so a 50,000 GPU cluster needs roughly 100TB/s to stay fed. According to NetApp, a traditional array delivers somewhere in the 40 to 80GB/s range, so reaching 100TB/s with conventional arrays means deploying “more than a hundred” of them. I ran the numbers myself, and how true that is depends on what you call an array. If NetApp means a single HA pair, 100,000GB/s ÷ 80GB/s works out to 1,250 of them at the optimistic end and 2,500 at the pessimistic end. If they mean a fully built-out, 12 HA pair ONTAP cluster, “more than a hundred” checks out. Either way, that’s a lot of namespaces, a lot of failure domains and a lot of people moving data around between them.
Here’s the thing though, Arindam Banerjee (NetApp’s Chief Platform and Technology Officer and one of the architects behind Novus) made the point that throughput isn’t actually what breaks first; metadata is. Every open, lookup and layout request lands on the same controllers that are trying to serve data. Training workloads are what he called “bimodal IO”: billions of tiny random reads for data loading, while terabyte-scale checkpoint writes land from every node at the same time. Those two patterns hate each other. Your data operations end up queued behind metadata operations, the pipe isn’t full and your GPUs sit idle.
And idle GPUs are expensive. GPUs are the biggest capital line item in an AI factory and the only thing in there that generates revenue. NetApp claims utilization in some AI factories falls into the single digits because storage can’t keep up, and they framed that not as a performance problem but as a margin problem, which I think is exactly the right way to pitch this to the people who’ll be signing the cheques.
Traditional NAS (think ONTAP as we know it) was built for enterprise concurrency and gives you data services, protection and governance. Parallel file systems like Lustre gave HPC the bandwidth, but at the cost of layout tuning and a proprietary client on every node. An AI factory needs both at once, plus agents hammering on it, and neither architecture was designed for that.
Enter Gary Grider
The best part of the keynote for me was Arindam bringing Gary Grider from Los Alamos National Labs on stage. If you’ve spent any time around HPC storage you’ll know the name; HPCwire named him a 2025 legend and he’s had his fingerprints on the burst buffer, PLFS, Lustre and pNFS. He also runs an environment with roughly six million cores and a trillion files, so when he talks about what breaks at scale, it’s worth listening.
His answer to “what breaks first?” was metadata, every time. Imagine a million cores all opening the same file, or 100,000 cores walking your file system at the same time; the metadata server falls behind, everything times out and the file system falls over.
The interesting nuance he added is that simply separating data and metadata isn’t enough, parallel file systems did that twenty years ago. In HPC, workloads tend to be homogeneous; big jobs compute for a long time and then dump everything at once. AI factories are the opposite. Gary talked about a project called Lattice, an open-source pNFS metadata server that breaks the metadata service itself into parts that can each scale independently and dynamically. He was also refreshingly candid that Lustre’s monolithic metadata server was a mistake they’d do differently today.
It turns out Arindam and George flew down to Santa Fe back in June to talk to Gary about Novus, and he’s been advising the R&D team since. Whatever you think of the rest of the announcement, that’s a pretty strong endorsement.
What Gary didn’t dwell on is who he built Lattice with. It came out of a collaboration between Los Alamos and PEAK:AIO, a storage software startup out of Manchester, and was released as open source under the Linux Foundation this summer. The Friday before INSIGHT, NetApp announced it’s acquiring PEAK:AIO (pending the usual closing conditions and regulatory approvals), with plans to bring its metadata and parallel namespace work to ONTAP. Put that together with the Santa Fe trip and Gary on stage, and it’s pretty clear NetApp has been lining this up for a while.
So what is Novus?
At its core, Novus splits the system into two independently scalable planes:
- The data plane runs on ONTAP. At launch that means AFF A90 HA pairs, the same A90 I wrote about back in 2024. The keynote was explicit that the Novus data servers will run ONTAP, so you get the integrity, resiliency, security, multi-tenancy and QoS you already know. NetApp’s solution brief fleshes out the multi-tenancy piece a bit more: tenant-level encryption, policy-based resource allocation and security controls that apply to both people and AI agents.
- The metadata plane is called the Novus Data Director, a software-defined control layer that runs on qualified x86 server infrastructure. A client asks the Data Director where a file lives, gets back a layout and then talks directly to the storage. Neither plane waits on the other.
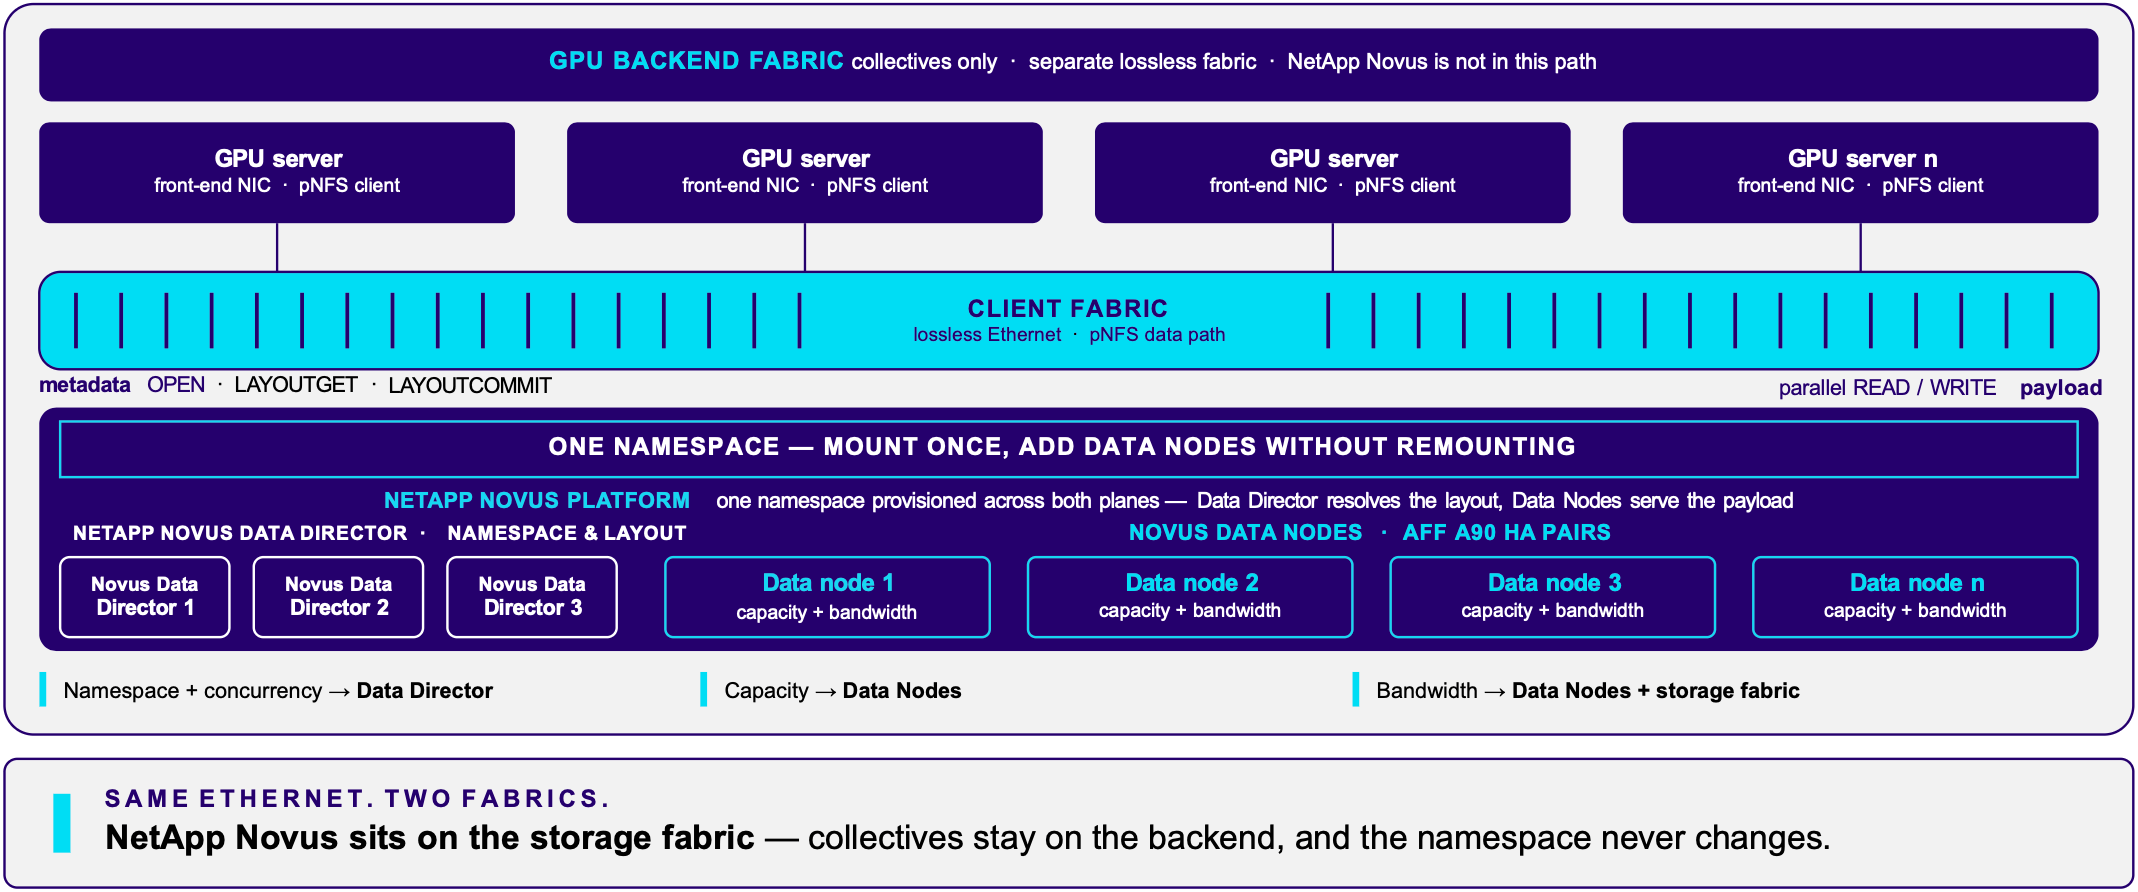
Arindam then went one level deeper: the Data Director itself is broken into three independently scalable subsystems, a protocol plane, a state plane and a catalog plane, each of which grows where the pressure is. Underneath all of that, metadata lives in a distributed key-value store that flattens the file system hierarchy, so lookups don’t have to walk a tree and there are no hot spots to melt down. If that sounds a lot like Gary’s Lattice description, that’s not a coincidence.
The way they get to 100TB/s is federation. NetApp was upfront that no single storage cluster, theirs or anyone else’s, can feed 50,000 to 100,000 GPUs. So instead of building a bigger cluster, Novus federates many ONTAP clusters behind the Data Director into one namespace, one mount and one file system tree. Add a cluster, add its throughput, and the application doesn’t know or care. NetApp says they’ve seen linear scaling in the lab every time they added building blocks.
The diagram above highlights one detail I haven’t seen talked about much: there are two fabrics. GPU-to-GPU collective traffic stays on its own separate, lossless back-end fabric, and Novus isn’t in that path at all. Novus lives entirely on the front-end client fabric, which is lossless Ethernet carrying the pNFS data path. That means your storage traffic never competes with your collectives, and there’s no dedicated storage back-end network to design, budget for and grow alongside everything else. Anyone who has tried to troubleshoot a congested fabric at 2 AM will appreciate that separation.
Here’s how it stacks up based on what was shared:
| Aggregate throughput | >100TB/s |
| Namespace | Single, zettabyte-scale |
| Data plane | ONTAP on AFF A90 HA pairs at launch |
| Metadata plane | Novus Data Director on qualified x86 servers (protocol, state and catalog planes) |
| Client access | In-kernel NFSv4.2 + pNFS Flex Files, nconnect, GPUDirect Storage |
| Proprietary client | None |
| Target | Neoclouds, hyperscalers, GPUaaS, large enterprise GPU clouds |
For context, George pointed out that the top of the IO500 today sits around 10TB/s, so 100TB/s is an order of magnitude beyond that. He also said the world shipped about 2,000 exabytes of data centre capacity last year, and Novus is designed so that all of it could theoretically sit in one namespace. I don’t expect anyone to actually test that claim, but it’s a fun way to frame “zettabyte”.
No proprietary client, and that’s a big deal
If you only take away one thing from this post, make it this: Novus uses pNFS with Flex Files, and pNFS ships with the stock Linux kernel. There is no NetApp client, no kernel module and nothing to install on your GPU nodes. Throughput comes from standard NFS features too: nconnect for multiple connections per mount and GPUDirect Storage, which lets data move directly between storage and GPU memory without bouncing through the CPU. As NetApp’s brief puts it, Novus “mounts like NFS”, which makes sense, because it is NFS.
Anyone who has run a parallel file system in production knows the pain here. Every kernel update, every new GPU generation, every CUDA bump means re-validating the storage client across thousands of node images, and your storage vendor effectively gets a vote in when you patch your fleet. Arindam’s line was that your storage vendor shouldn’t get that vote, and I couldn’t agree more. It’s also consistent with what NetApp did with AFX, which I noted last year as having no proprietary client software. NetApp helped drive pNFS into existence as an IETF standard, so it’s nice to see them get a big payoff from that work some twenty-odd years later. Gary joked that he’s spent 26 years trying to get pNFS adopted, and it looks like that’s finally happening.
Metadata as knowledge
The last idea Arindam left us with is the one I think will matter most down the road. Once metadata has its own tier, its own plane and its own catalog, it stops being bookkeeping and becomes something you, or your agents, can query: provenance, lineage and meaning across a trillion files. Gary talked about things like predicate pushdown and virtual lakehouses that become possible once the metadata is broken out. Tie that into the AI Data Engine announcements from the same keynote and you can see where NetApp is heading, but that’s a topic for another post.
How this fits with AFF and AFX
A fair question is where Novus fits now that NetApp has AFF, AFX and Novus all running ONTAP. Jeff Baxter, NetApp’s VP of Product Marketing, put that question to the Novus VP of Product Management on NetApp On Air after the keynote, and the answer went like this:
- AFF remains the mainstream workhorse for enterprise workloads.
- AFX gives you that combination of capacity, performance and disaggregation for specific use cases, and it’s the architecture I covered at INSIGHT 2025.
- Novus is for when scale is the whole point: AI gigafactories, with next-generation EDA workflows called out as well.
Arindam described the progression nicely in the keynote: NFS disaggregated storage from the server, virtualization disaggregated data services from the protocol, AFX disaggregated performance from capacity, and now Novus disaggregates metadata from data and then disaggregates the metadata service itself. As someone who has watched ONTAP evolve for a long time now, I like that NetApp is extending ONTAP here rather than bolting a brand-new file system onto the side and asking us to trust it.
What I’m watching for
As exciting as this is, there’s a lot we don’t know yet. NetApp has said this is not vaporware and that it’s landing as a product “very soon”, with timelines, ecosystem partners and more architecture detail coming in today’s Day 2 keynote at 9:00 AM Pacific. Here’s what I’ll be looking for:
- Availability and timelines. “Very soon” is not a date.
- Minimum footprint and pricing. Novus is clearly aimed at Neoclouds and hyperscalers, but NetApp also said it’s meant to serve “every use case.” What does the smallest sensible Novus deployment look like, and is it within reach of a large enterprise that isn’t building a gigawatt facility?
- Data Director resiliency. The data plane inherits ONTAP’s resilience, but the Data Director is new code on x86. How does it handle failure, and what does the HA story look like? The architecture diagram shows three Data Directors, which suggests there’s more than one of them for a reason, but I want to hear how failover actually works. The Novus team hinted that failure handling will be a big part of today’s session.
- Client requirements. NetApp says “supported Linux client environments.” I want to know which kernel versions and distributions are qualified for Flex Files at this scale.
- Operations at scale. Federating many ONTAP clusters behind one namespace is great for the application, but someone still has to upgrade, expand and troubleshoot all of those clusters. The team talked about a provider- and tenant-centric interface built to reduce operational toil, and I want to see it.
- Real-world numbers. 100TB/s is a design target validated in NetApp’s labs. I’d love to see the first customer references.
- What comes after the A90? Launch is A90 only. I half expected AFX nodes to be next, but the solution brief points somewhere else: future software-defined options where both the metadata services and the ONTAP data services run on qualified third-party hardware. That’s a big shift for ONTAP and I’ll be very interested to see how it plays out.
All of the above is based on the keynote, the livestream, NetApp’s launch blogs and the Novus solution brief, and some of it may change by the time Novus ships. I’ll endeavour to add corrections below should any of it change, and I’ll be covering the Day 2 keynote in a separate post.
For years the knock on NetApp in the HPC and AI training world was that ONTAP was great for enterprise data but not the thing you’d point 50,000 GPUs at. With Novus, NetApp is making a serious attempt to change that without throwing away the parts of ONTAP we’ve all come to trust. Watch this space.


